Data & AI systems,
built to run in production.
I'm Henry Clavo — a Technology Consultant, Data Scientist, and AI Engineer. I help teams design and ship reliable data platforms and applied AI on Databricks, Microsoft Fabric, and the modern cloud.
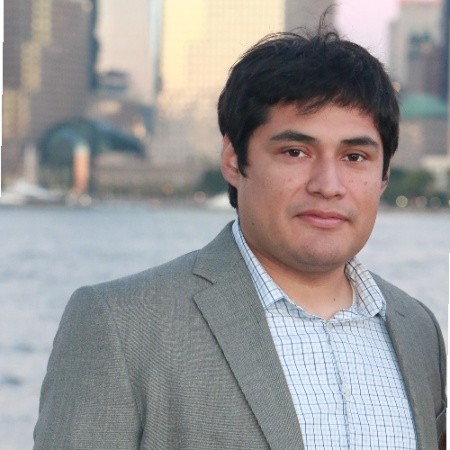
How I help teams
Advisory
Architecture reviews, platform strategy, and delivery leadership for teams building modern data and AI systems.
Engineering
Hands-on delivery of Lakehouse, streaming, and agentic AI systems on Databricks, Microsoft Fabric, and Azure.
Enablement
Workshops, talks, and coaching to level up engineering teams on modern data platforms and applied AI.
Focus areas
- Data Strategy
- AI & Autonomous Agents
- Databricks
- Microsoft Fabric
- Big Data Engineering
- Cloud Architecture
- Speaking & Workshops
Speaking & Work With Me
I speak at conferences, meetups, and podcasts on practical data engineering and applied AI. If you'd like me at your event or need help with a data or AI program, get in touch.
Data Engineering & AI
Where modern pipelines, lakehouses, and generative AI meet — patterns that hold up in production.
Data Governance for Generative AI
Building data trust for LLMs: lineage, access control, PII handling, and evaluation.
Snowflake to Databricks Migration
Real-world lessons from migrating and optimizing pipelines on Azure Databricks.
AI Leadership
Responsible adoption, governance decisions, and leading teams through AI change.
Past venues
- Hevo Data
- Data Science Connect
- Turbo360
- Astera Software
- TheAssociation.Ai
Selected talks & podcast appearances
The Future of Data Engineering & AI
How data engineering is changing under generative AI: lakehouse patterns, pipeline reliability, and what it takes to run production data systems in healthcare and government.
Building Trust in AI: Data Governance and Data Management for Generative AI
Panel on data governance for generative AI — how lineage, access control, PII handling, and evaluation create the foundation for trustworthy enterprise GenAI.
Migrating & Optimizing Data Pipelines: Snowflake → Azure Databricks
Real-world Snowflake to Azure Databricks migration: lakehouse architecture, pipeline optimization, cost, and automation lessons from production workloads.
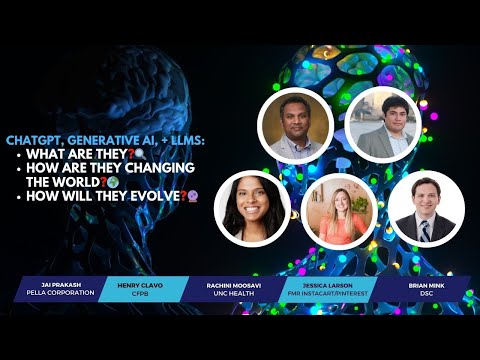
ChatGPT, Generative AI, Large Language Models
Panel on ChatGPT, generative AI, and LLMs — how they work, where they break, and how enterprises are putting them into production responsibly.
Writing on data platforms and AI governance
In-depth, vendor-neutral guides drawn from production work — how to govern data for generative AI and how the major lakehouse platforms actually compare.
- Guide
Data Governance for Generative AI: A 2026 Playbook
How to build data governance for generative AI: trust, access control, lineage, PII, RAG guardrails, and evaluation — with examples and an FAQ.
Read the guide → - Guide
Apache Iceberg vs. Delta Lake: A 2026 Comparison
Apache Iceberg vs. Delta Lake compared: metadata design, schema and partition evolution, engine support, and how to pick a table format.
Read the guide → - Guide
Databricks vs. Snowflake: A 2026 Comparison
Databricks vs. Snowflake compared: lakehouse vs. cloud warehouse, pricing, governance, AI workloads, and how to plan a migration.
Read the guide → - Guide
Databricks vs. Microsoft Fabric: A 2026 Comparison
Databricks vs. Microsoft Fabric compared: Delta Lake vs. OneLake storage, compute and pricing models, governance, and Azure ecosystem fit.
Read the guide →
How I work
Rigor over hype
Systems that behave well in production — measured, observable, and boring where it matters.
Simplicity by default
Fewer moving parts. Clear ownership. Architectures the team can operate a year from now.
Business outcomes
Every model, pipeline, or agent ties back to a decision, a metric, or a dollar.
Let's talk
Open to consulting engagements, speaking, and interesting problems in data and AI. Messages come straight to my inbox.